For years, the data center was a predictable place. Racks of CPU servers handled databases, web traffic, and enterprise applications, and you could roughly estimate capacity based on clock speeds and core counts. That world is gone. The workloads that matter now - training AI models, running real-time inference, simulating physical systems, processing massive sensor streams - do not fit the old mold. They demand something fundamentally different. That something is accelerated computing, and it is reshaping not just hardware roadmaps but the entire economics of computation.
I have spent the better part of a decade watching this shift happen from the inside. When I first started working with GPU acceleration, it felt like a niche tool for researchers who needed to crunch matrix multiplications faster. Today, it is the backbone of modern AI computing, high-performance computing, and even cloud computing at scale. The reason is straightforward: general-purpose CPUs hit practical limits on parallelism and power efficiency years ago. Accelerated computing solutions solve that bottleneck by pairing CPUs with specialized processors - graphics processing units, Tensor Cores, and dedicated AI accelerators - that handle the heavy parallel math while the CPU manages orchestration.
Where the Old Model Breaks Down
Consider training a large neural network. A single training run can involve billions of floating-point operations spread across millions of parameters. On a CPU-only cluster, that run might take weeks and consume enormous power. With parallel processing on GPUs, the same task finishes in days or even hours. That difference is not incremental; it is transformational. It means a team can iterate on a model ten times in the time it used to take for one. That speed changes how you approach research, product development, and deployment.
But acceleration is not only about training. Inference - the stage where a trained model actually makes predictions or decisions - benefits just as much. In production, latency matters. A recommendation engine that takes two seconds to respond loses users. An autonomous vehicle that hesitates at an intersection creates risk. Accelerated computing solutions handle inference workloads with the kind of low-latency, high-throughput performance that CPUs alone cannot deliver. This is why data centers are being retrofitted with GPU servers and why cloud providers now offer instance types built around NVIDIA GPUs and CUDA-optimized frameworks.
The Software Stack Matters as Much as the Silicon
Hardware gets the headlines, but the real leverage comes from the software stack. CUDA, the parallel computing platform and programming model from NVIDIA, turned GPUs from graphics chips into general-purpose accelerators. Before CUDA, writing code for a GPU meant learning graphics shader languages. After CUDA, researchers and engineers could write C++ extensions that mapped naturally to parallel problems. That opened the door for deep learning frameworks like TensorFlow and PyTorch to run efficiently on GPU hardware, and it created an ecosystem where libraries for everything from molecular dynamics to financial risk modeling were already accelerated out of the box.
One thing I have learned the hard way is that acceleration is not automatic. You cannot just drop a GPU into a server and expect every workload to speed up. The software needs to be written or adapted to exploit parallelism. That is where the ecosystem around CUDA, cuDNN, and TensorRT becomes critical. These libraries handle the low-level optimization so that application developers can focus on their models and data pipelines. The result is that even complex workflows - like training a transformer-based language model or running real-time object detection on video streams - become practical on standard data center hardware.
From the Data Center to the Edge
Accelerated computing is not confined to giant server rooms. Edge computing pushes processing closer to where data is generated - factories, retail stores, hospitals, vehicles. At the edge, power and space are limited, and latency requirements are strict. A graphics processing unit or Tensor Core processor that fits in a compact form factor can run inference on sensor data locally, without sending everything to the cloud. That matters for applications like predictive maintenance on industrial equipment, where a millisecond delay could mean missing a critical vibration signature, or for medical imaging devices that need to flag anomalies during a procedure rather than after uploading scans.
The same principles apply in reverse. Cloud computing gives you elasticity, but it also introduces network latency and bandwidth costs. By using accelerated computing solutions at the edge, organizations can filter and preprocess data before sending it upstream, reducing the load on data center networks and lowering overall expense. This hybrid model - edge plus cloud - is becoming the standard architecture for industry-specific AI deployments in manufacturing, healthcare, and retail.
DGX Systems and the Appliance Model
For teams that want a turnkey experience, integrated systems like NVIDIA DGX have become popular. These are not just servers with GPUs bolted in. They are engineered appliances with optimized power delivery, cooling, and networking, preloaded with the software stack needed for AI training and inference. I have seen organizations cut their deployment time from weeks to hours by adopting DGX systems instead of assembling their own clusters. The trade-off is cost: an integrated system costs more upfront than a DIY approach. But for many teams, the time saved and the reduction in integration headaches justify the premium.
That said, not every organization needs a full DGX system. Cloud instances with GPU acceleration offer a pay-as-you-go model that works well for experimentation and variable workloads. The key is matching the infrastructure to the workload profile. A research lab that trains one model per quarter might be better off renting cloud GPU time. A company running continuous training and inference pipelines likely benefits from dedicated on-premises hardware.
Quantum Computing and the Long View
It would be irresponsible to talk about accelerated computing without mentioning quantum computing. Quantum is not a replacement for classical acceleration; it is a different paradigm entirely, suited to problems like cryptography, molecular simulation, and optimization that are intractable for classical machines. NVIDIA is already investing in quantum computing simulation tools that run on GPU-accelerated hardware, because even quantum researchers need classical compute to design and test quantum algorithms. The practical timeline for fault-tolerant quantum computers is still measured in years, but the groundwork being laid today depends heavily on the same accelerated computing solutions that drive AI and HPC.
Practical Advice for Decision Makers
If you are evaluating whether to invest in accelerated infrastructure, here are the questions I would ask:
- What is the actual bottleneck in your workflow? Profile your application to see if it is compute-bound, memory-bound, or I/O-bound. Acceleration helps most with compute-bound parallel tasks.
- Do your software dependencies support GPU acceleration? Check whether your frameworks, libraries, and custom code can leverage CUDA or other acceleration platforms. Rewriting code for parallelism is expensive.
- What is your tolerance for complexity? Integrated systems reduce friction but limit flexibility. DIY clusters offer more control but require deeper expertise.
- How will your workloads grow? Accelerated computing scales well for parallel problems, but not all problems parallelize. Understand the scaling characteristics of your algorithms.
- What is the total cost of ownership? Factor in hardware, software licenses, power, cooling, and staff time. Sometimes cloud acceleration is cheaper; sometimes on-premises wins.
These are not trivial decisions. I have seen teams overspend on hardware that sat idle because their software could not use it, and I have seen teams underspend and lose months of productivity waiting for jobs to finish. The right answer depends on your specific data, models, and operational constraints.
The Bigger Picture
Accelerated computing solutions are not a fad. They are a response to a fundamental shift in what we ask computers to do. We are no longer just processing transactions and serving web pages. We are training neural networks with billions of parameters, simulating climate systems, designing new materials, and running real-time AI in factories and hospitals. Those tasks demand hardware that is built for parallelism, and software that can exploit it efficiently.
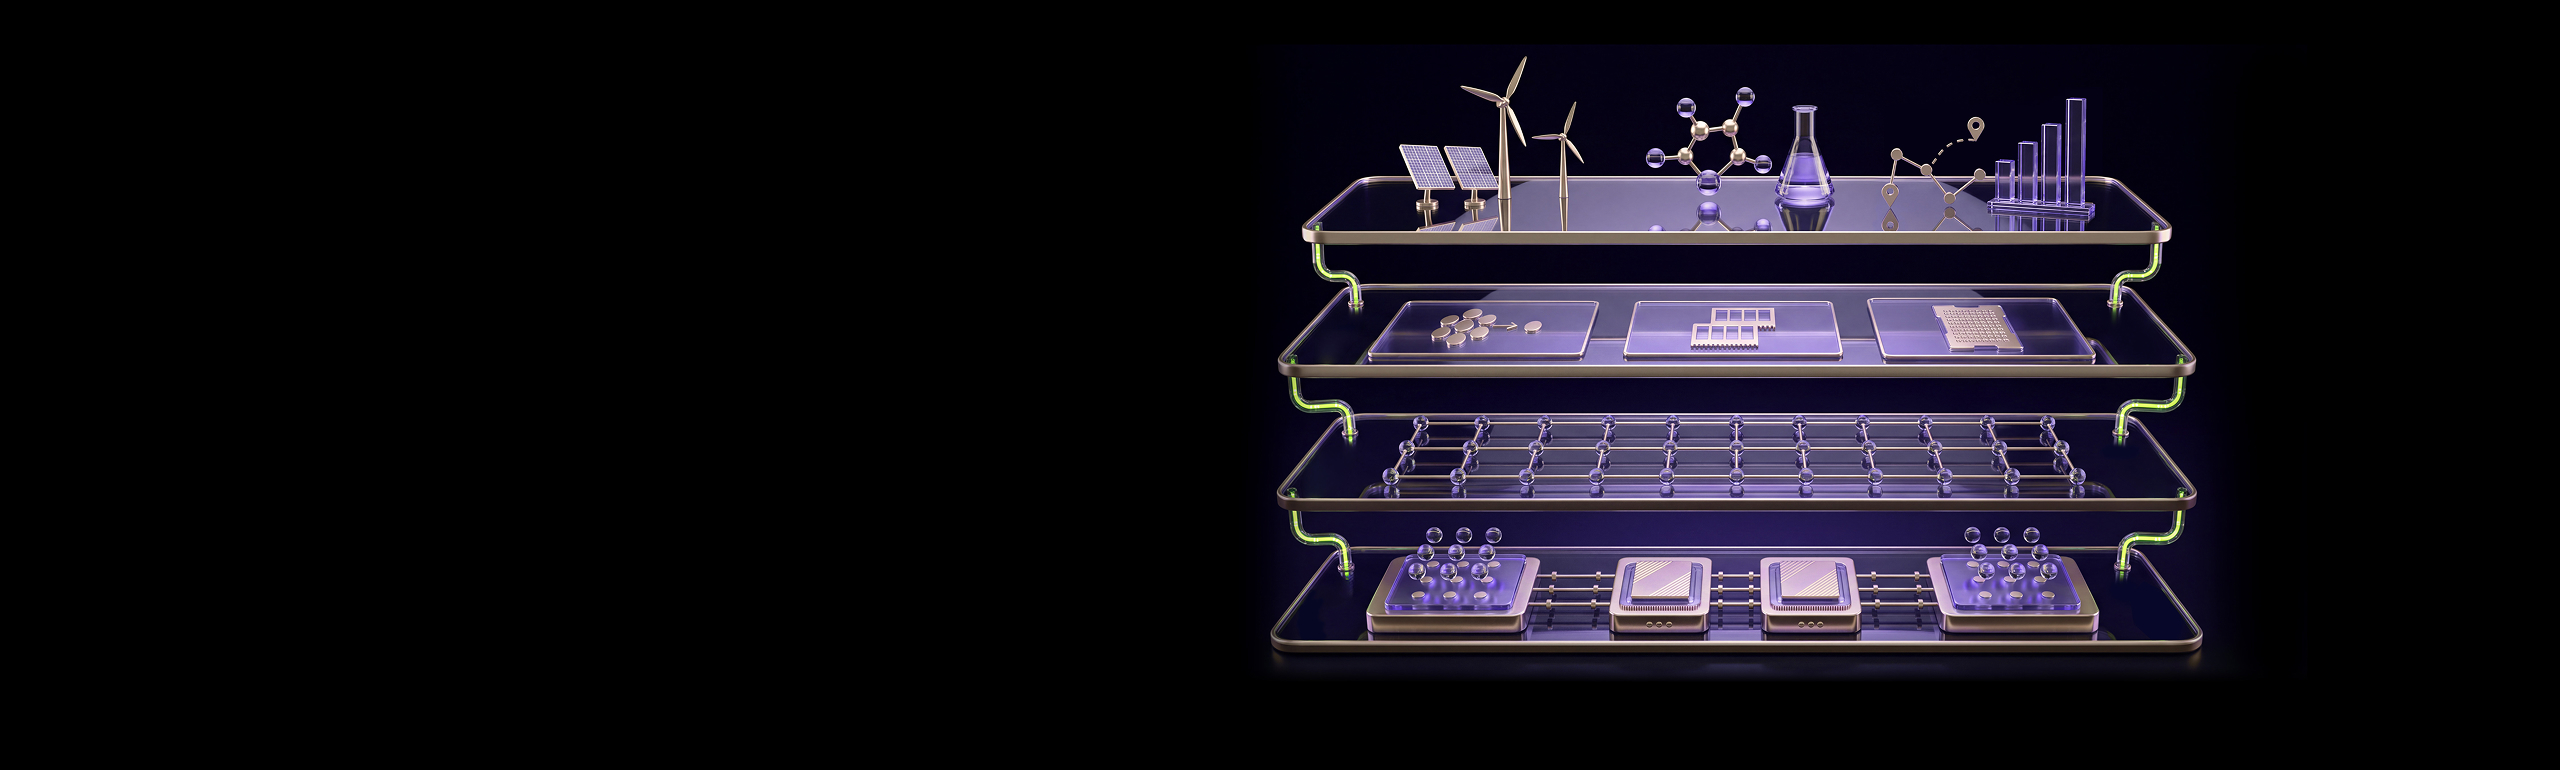
NVIDIA has been at the center of this transformation, but the ecosystem is broader than any single company. The combination of GPU acceleration, CUDA, deep learning frameworks, and cloud infrastructure has created a platform that enables innovation across industries. Whether you are building the next generation of AI models, optimizing a data center for high-performance computing, or deploying industry-specific AI at the edge, accelerated computing is the foundation you will build on.
The old data center was about keeping the lights on. The new one is about making the impossible possible. That is a shift worth paying attention to.